
A/B testing and experiments
Create and run A/B tests in Ordinary with variants, traffic split and page and audience targeting, scored on reconciled revenue with peek-safe statistics.
 Written by The Ordinary Team · Updated
On this page
Run A/B tests directly in Ordinary and score every variant on the real orders your store actually shipped — not clicks, not sessions, not a vanity uptick. Set a test up in a couple of minutes; Ordinary handles the traffic split, the statistics, and the revenue attribution.
Left nav → Experiments.
Create a test in Ordinary
Click New experiment, give the test a name and the page it runs on, and choose how its groups are delivered: Visual editor (build the variant by clicking elements on your page; Ordinary puts the changes on your theme when the test starts) or Theme code (your theme ships both versions; Ordinary checks the markup is live before the test starts). The test is created as a draft that opens straight onto its test page. A theme-code draft can still be switched to the visual editor from its page; once a test has started, how it is delivered is fixed. (Splitting visitors between two different URLs, scoping to a channel up front, or importing from a legacy tool? The create dialog links to a full form that covers those in one pass.)
Everything about a test — reporting and configuration — lives on one page, organised into tabs. Results shows how the test is doing (it’s where you land once a test is running); the config tabs below are editable while the test is a draft or paused:
-
Test groups — add 2–10 groups (the visual editor works with up to 4) and set the traffic split (50/50, 80/20, whatever you need). The first group is your control — your current page, unchanged. Drag the split bar to move traffic between groups in 5% steps, or type exact percentages. You can also change the split while the test is running — ramp a winner up gradually, or set a group to 0% to stop sending it traffic without ending the test. Shoppers already in the test keep their group, so only new visitors are affected, and each split is scored from the moment you save it. Which groups exist and where they point stay fixed once a test starts.
-
Modifications — what each group changes on the page. Author edits visually (click any element on your storefront and change its text, style, image, or visibility), or ship variant content in your theme code using the attribute strings from the results page — both are listed here per group.
-
Targeting — who enters the test and where it runs. Limit entry to a device type (mobile, desktop, tablet — e.g. test a mobile-only layout change on mobile traffic alone), a visitor type (new or returning — e.g. run a first-time-buyer offer at people who’ve never visited, without touching your repeat customers), and/or a traffic source, and the currency they’re shopping in. Sources are grouped: Paid (Meta ads, Google ads, TikTok ads, Microsoft ads, other paid social — Pinterest, Snapchat, X, LinkedIn, Reddit), Owned (Klaviyo, other email/SMS), and Earned (organic search, organic social, AI assistant, referral, direct). So you can run a landing-page test on TikTok ads only, or try different copy on people arriving from ChatGPT. A shopper counts as returning once they’ve visited your store in an earlier session; browsing privately, on a new device, or with site data cleared reads as new. Everyone else sees your normal site; the filters decide who enters, and once a shopper is in they keep their assigned group on every return visit, whatever device or source they come back through — so a new-visitor-only test keeps scoring the people it enrolled after they become returning visitors. Set the page URL pattern — a trailing
*matches a whole section (e.g./products/*). For multi-page tests this tab also holds persistence: extra pages where shoppers already assigned to a treatment group are taken back to their group’s page (new visitors are never pulled in from these pages, control shoppers are never redirected, and the cart and checkout are never touched), plus a sticky window — how many days each shopper keeps their assigned group, counted from their first visit (default 365).Currency targeting is the one to reach for on a price test. It matches the currency the shopper is actually seeing prices in, so someone in Ireland checking out in GBP lands in your GBP group — which is the grouping a pricing question is really about. Shoppers in a currency you haven’t selected see your normal page.
Region targeting keeps a test inside one part of the world — for example your UK storefront only — even when your pages share the same URLs across countries. Pick one or more countries, and/or type the handles of your Shopify markets (find them in Shopify admin under Settings → Markets); if you set both, a shopper has to match both. It goes by the country and market your store is showing the shopper (the country they picked in your store’s country selector, or the one Shopify detected for them), not by their IP address. Shoppers outside the region see your normal page and never enter the test. If Ordinary can’t tell which region a shopper is in, they’re left out of the test rather than let in. Like every targeting filter, it decides who enters: a shopper who joined from the UK and later switches to another country keeps their assigned group.
“Also run on these pages” lets one test start on more than one page. A test has a single page URL, which covers “this page” or “this section” — but an offer test usually spans a product page and the landing page that sells it, and those don’t share a prefix. Add the extra paths here, one per line; they follow the same rules as the page URL, so a trailing
*still matches a whole section. If you find yourself listing many pages, a*pattern is usually the better tool.This tab also holds the exclusion group. If two of your tests can reach the same shoppers, a shopper who lands in both makes each result harder to trust — you can’t tell which change moved the number. Give both tests the same exclusion group label and no shopper will ever be in both: each one is put into one test or the other, and stays there. Shoppers already in a test keep it, so adding a label to a test that’s already running never removes anyone — it only affects who joins from that point on. Leave it empty (the default) when your tests don’t overlap, or when you’re happy for them to run together. Each test then reaches its full audience and reads its result sooner.
Tests in a group share the shoppers equally unless you say otherwise. To send more of them to one test, give each test in the group a share of the group’s traffic — a relative weight, so 70 on one test and 30 on the other sends roughly seven in ten new shoppers to the first. The shares are balanced across the group automatically, and a test you leave blank counts as an equal share. As with the label itself, changing a share only affects shoppers who haven’t joined yet.
-
Goals — the primary metric that decides the winner (revenue per visitor by default, or conversion rate, average order value, or reach rate), optional guardrail metrics that must not regress (refund rate, bounce rate, add-to-cart rate, 30-day repeat purchase, reach rate), your hypothesis, and the attribution window.
Reach rate measures whether visitors get from the test page to a page you choose — the share of visitors who reach that goal page within a set time after seeing the test. It’s the metric for changes whose job is to get people somewhere rather than to change the order itself: a navigation change, a collection page that should send more shoppers into product pages, a landing page that exists to get people to the offer. It works as the primary metric or as a guardrail (to catch a variant that quietly stops people getting where you want them). Choosing it either way adds a Reach goal card to the Goals tab with two fields. Goal page is a path on your store: a bare path (
/pages/offer) is that exact page, and a trailing*(/products/*) matches everything under it. Query strings are not supported — the goal matches the page path only. Within (minutes) is how soon after seeing the test page the visitor has to get there; 30 minutes is the default and covers a normal browsing session. A test that uses reach rate can’t be saved without a goal page.The attribution window is how long after a shopper first sees the test their orders still count toward it. The default is 14 days, and it fits almost every test — most orders happen within a day or two of the visit. Lengthen it only if your shoppers genuinely take longer to decide, and know the trade: a long window also starts counting repeat purchases that would have happened anyway, which flatters whichever group happens to contain more of your existing customers.
It’s easy to mix this up with the sticky window on the Targeting tab, because both are counted in days from the same moment. They do different jobs: the sticky window controls how long a shopper keeps seeing their assigned version, and the attribution window controls how long their orders count. Ordinary won’t let you set the sticky window shorter than the attribution window, since that would mean showing someone the original page while their purchases still counted toward the version they used to see.
-
Preview & QA — per-group links that force a page load into that group so you can QA it. Preview visits write no cookie and record no exposure, so your test data stays clean. Links go live once the test starts.
-
Theme changes — if this test changes wording or images in your theme, this shows you exactly what Ordinary added, line by line, and lets you take it back out. See Removing a test’s changes from your theme.
Click Start when you’re ready. Ordinary serves the split through your store — no separate testing tool, no DNS or tag-manager setup. Bucketing is sticky (a shopper always sees the same group), and results start flowing within minutes.
For same-page tests, the Start or Resume confirmation checks the live pages before you confirm and displays any styling warnings. Verify on live site also works on draft and paused tests without starting them. Styling warnings are advisory, not a guarantee that every template looks correct; check each version yourself. If a check cannot run, you’ll see that it is unavailable rather than a passing result.
If your team adds the test to your theme by hand, pressing Start first checks your live page for this test’s markup. If it isn’t there yet, the test doesn’t start: you see what was checked, and if the page carries markup from an older test (for example one you ended and re-created), Ordinary names that test so you know which ID to update in your theme. Fix the markup and press Start again, or choose Start anyway if you know it’s about to go live. When you end a test like this, Ordinary checks the page again and tells you whether the test’s markup is still there and whether any of it is showing. A version your theme ships hidden stays hidden once the test ends; one that relied on Ordinary to hide it shows next to the original until it’s removed.
If two running tests edit the same element on a page they share, Ordinary shows a warning at the top of each test’s page — and again the moment you publish from the editor — naming the other test and the elements they have in common. Two tests editing one element show visitors a mix of both, so neither result is a clean read of its own change. Nothing is blocked; the fix is to move one test to a different element or page, give both tests the same exclusion group so no shopper is in both, or end one of them.
One thing to know when you end a test: shoppers go back to your normal page immediately, but orders from people who saw the test can still land for the length of the attribution window. So the numbers keep settling for up to 14 days (or whatever window you set) after you stop it. That’s deliberate — cutting it off at the moment you press Stop would throw away real orders from shoppers who saw the test just before it ended. If a result is close, wait out the window before calling it. The When this test was ended card on the Results tab shows how the result read at the moment you stopped it next to how it reads now.
Whole-page redesigns: use a split-URL test
Shopify allows at most 25 sections on one page template. A same-page test keeps both versions of the page in that one template, so the original’s sections and the new version’s sections all count toward the same 25 — including sections you’ve hidden or disabled. Changing a headline, an image, or a single section fits on almost any page. Swapping in a completely new design only fits when the page has roughly 12 sections or fewer, and a new version that reorders sections it shares with the original has to repeat them, which uses up the room faster.
When you enter a page for a same-page test, Ordinary checks how many sections it already shows and warns you once it reaches 20. The check only sees sections that appear on the live page, so the real number can be higher than the warning says.
For a whole-page redesign, use a split-URL test instead. Build the new
page as an alternate template in your theme — Shopify shows it at the same
address with ?view= and the template’s name added (for example
/?view=v2). Then create the test from the full form, choose
Multi-page, and give the control group your original address and the
new-page group the ?view= address. Your ads keep pointing at the
original address; Ordinary sends shoppers in the new-page group on to the
new page and reports the test by group.
The trade-offs, so nothing surprises you:
- Shoppers in the new-page group are redirected before the original page appears, so their first page load takes a moment longer.
- The new page’s address shows the
?view=part in the browser. - Shopify’s and Meta’s own reports can show the two addresses as separate landing pages. Compare the groups on the test’s Results tab.
Who counts as a visitor in a test
A shopper counts in a test from the moment they could actually see it — not just because they landed on a page the test targets. That keeps shoppers who saw nothing different out of the result, so the lift you read is the lift the change made.
- Tests that change part of a page (your own theme markup, or
changes made in the editor): a shopper counts once the test’s content
is on the page they’re viewing and Ordinary isn’t hiding it from them.
- Started the test before its markup was live? Shoppers aren’t counted until it is.
- Page pattern wider than the pages that carry the change (say
/products/*, with the change on one product template)? Only shoppers on the pages with the change are counted. - A test inside a group of another test — a section that only exists on a new homepage, for instance — counts only the shoppers in that group, in both of its own groups.
- Content tucked away until tapped still counts — a closed mobile menu, an accordion, a tab. What matters is that it’s on the page for that shopper, not whether it was on screen.
- Content a script adds to the page after it loads is checked again for a few seconds; content that only appears later than that isn’t counted on that page view.
- Split-URL tests count a shopper when they land on the test’s trigger page, as before.
- Preview links never count.
Once a shopper is counted they stay in the test, and their orders count toward it for the attribution window from that moment.
Tests that were already running when this rule was introduced keep every shopper they had already counted; only shoppers counted from then on follow it. If an older test’s page pattern covers more pages than carry its change, or it sits inside another test, its early numbers may include shoppers who never saw it — a fresh test gives the cleanest read.
How many tests you can run
The Free plan includes one A/B test: the first one you create. It’s there so you can run a real test on your own store, with your own traffic, and see what the feature does before paying for it. Ending, archiving or deleting that test doesn’t free up another one.
On Free, only that first test can be started or resumed. Any other test on the account — for example one built while you were on a bigger plan — shows Start or Resume greyed out with an Upgrade to run link beside it. Its setup and results stay readable.
When your store moves to the Free plan from a bigger one, your first test keeps running and every other test that is running or paused is ended. Drafts stay as drafts. Ended tests keep their results, and an ended test can’t be restarted — upgrade and create a new one to run it again.
Starter and Advanced remove the limit — run as many as you like, at the same time or one after another.
If you’re on Free and the New experiment button is greyed out, you’ve used your test. Your test and its results stay readable whatever plan you’re on.
Archived tests stay readable too, but the Experiments list hides them until you ask: the status filter at the top of the list is a set of checkboxes, and Archived starts unticked. Tick it to see archived tests alongside the rest.
What the dashboard shows
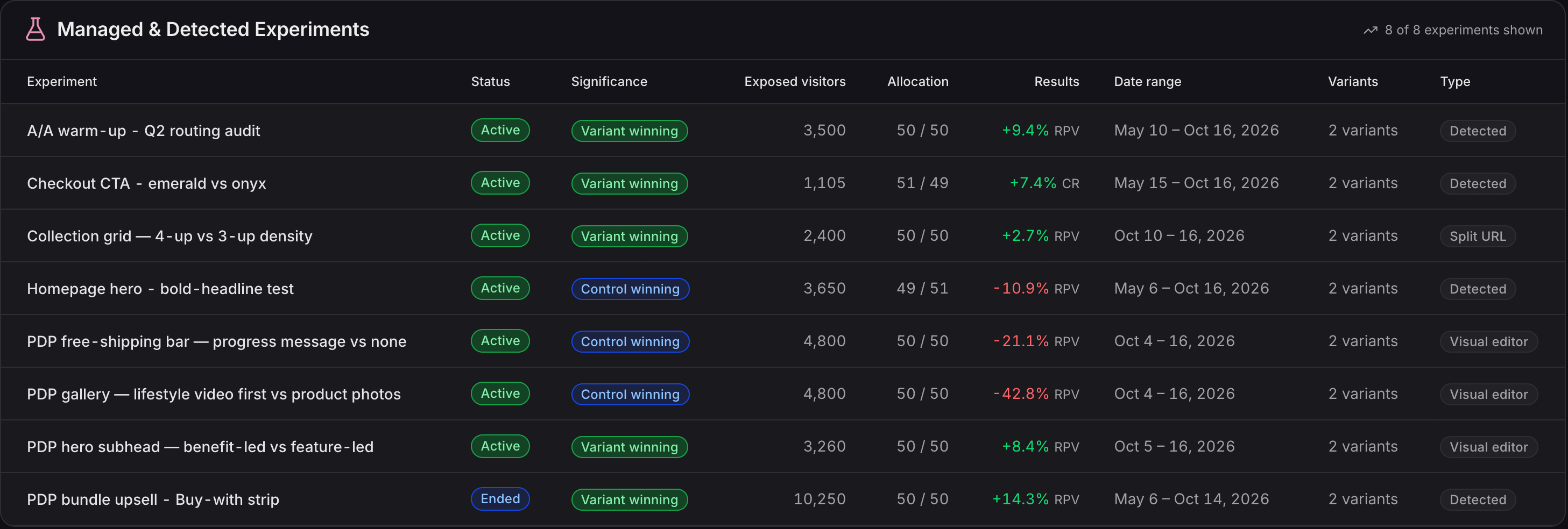
The Experiments list shows every test with its type, status, when it ran (from launch to the last visitor seen), how many groups it has, how many visitors have been exposed, a headline result, a plain-English verdict, and the traffic split actually observed. Type says how the test is delivered: Split URL (each group is its own page), Visual editor (built in Ordinary’s editor), Theme code (the variant lives in your own theme code) or Detected (run by another tool). The headline result is the best variant against the control on the metric the test optimises (revenue per visitor, conversion rate or average order value, as labelled) — it goes negative when the control is ahead, so a test the control is winning still shows by how much. Once a test is ended, its row stops adding visitors — only shoppers who saw the test before the end count — but keeps counting those shoppers’ orders through their attribution window, even after the end, the same way the test’s page does. The list figure is a plain ratio; the page’s headline clips each visitor’s revenue at the test’s cap (the top 5% of your buyers’ revenue over the 90 days before it started), so the two can differ on a test with one big order. Clicking into a test opens the detail view.
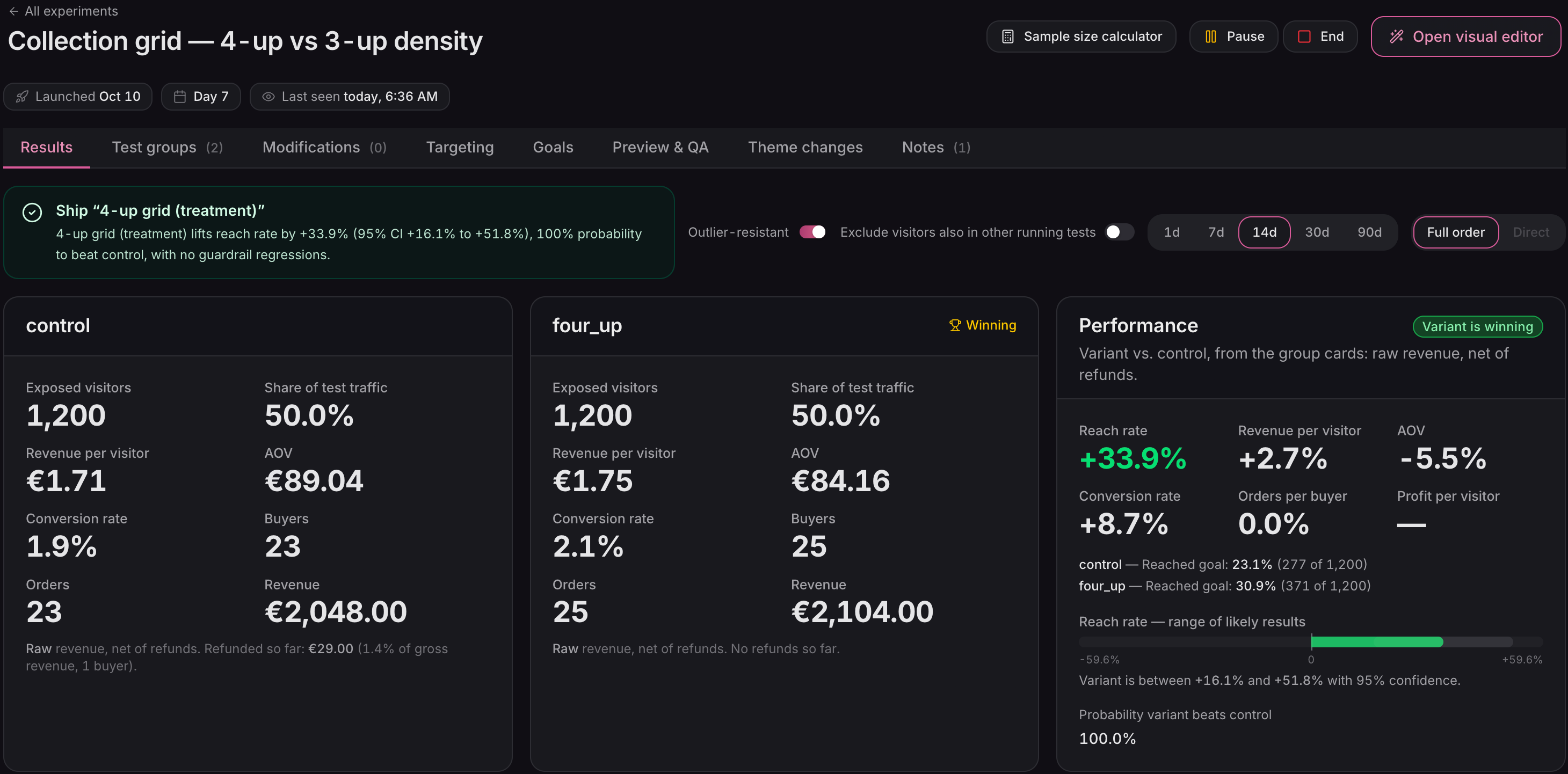
Under the test’s name a row of chips shows when it launched, which day of the test it is (the launch day is day 1), when a visitor was last seen and, once you end it, when it ended and how many days it ran. The detail view shows:
- Per-arm results for the visitors who saw each variant — revenue per visitor, average order value, conversion rate, buyers, orders and revenue. Every number on a card comes from the same revenue, so they check against each other: revenue per visitor is revenue ÷ visitors, average order value is revenue ÷ orders (not buyers — a shopper who orders twice counts twice), and conversion rate is buyers ÷ visitors. The card says which revenue it is: Outlier-resistant (each visitor’s revenue capped at a fixed amount set when the test started — the top 5% of your buyers’ revenue over the 90 days before — the default; the badge’s tooltip shows the amount) or Raw (the toggle off). Revenue is always net of refunds: every refund recorded against that group’s orders so far is already taken out. The line under the numbers shows the money actually refunded to customers so far and what share of the group’s revenue before refunds that is; when order edits swapped items without returning any money, one more line counts those orders.
- Lift — how the variant performs against the control, with a plain-English “range of likely results” (the statistical confidence interval, named so it’s actually readable). The companion lifts next to it — average order value, conversion rate and orders per buyer — are worked out from the numbers on the group cards, on the same revenue, and they multiply out: (1 + revenue-per-visitor lift) = (1 + conversion-rate lift) × (1 + order-value lift) × (1 + orders-per- buyer lift). Profit per visitor starts from the same revenue (see Profit per visitor below).
- When this test was ended — on a test you’ve ended, the result as it read at that moment (only orders placed by then, from visitors who had seen the test by then), next to what it reads now, how many visitors still had an open attribution window when you stopped it, and the buyers and orders that have arrived since. It uses the same revenue as the group cards, net of the refunds recorded by the time you stopped the test — what the page would have said then — so the two columns differ only by the orders and refunds that arrived later. The verdict banner says the test has ended rather than “keep running”.
- Stop “[group]” — it’s losing — the verdict banner says this, naming the losing group, when a running test’s variant is behind and has 10% or less chance of beating control on the test’s goal, with at least 5 buyers in each group and 20 in total. It doesn’t wait for statistical significance: stopping a loser needs less certainty than shipping a winner, because every extra visitor sent to it costs revenue now. A significant loss still reads “Keep control”. The line under it names the metric the chance is measured on.
- Leaning “[group]” / Leaning control — every test is also read on money: revenue per visitor, checked against conversion rate and, when you can see costs, profit per visitor. When there’s an 80% or better chance a group earns more (or less) per visitor, and conversion and profit don’t point the other way, the banner says which way the test leans and how sure it is, with the numbers. It isn’t statistically conclusive, so it reads “Leaning”, but it gives lower-traffic stores an answer they can act on instead of waiting months. An ended test that leaned reads “[group] was ahead” or “control held”.
- Leaning “[group]” — 87% chance it’s ahead (directional read, 49 visitors) — a running test with no strict call and no money lean yet, where the test’s goal already leans 80% or more one way. The headline carries the visitor count and the line under it says how many buyers (or goal visits) it rests on, so it reads as the direction so far, not as a result. When a line adds “Planning estimate: ~N more visitors”, that is a rough guide to how much more traffic a call needs, not a promised decision date. “On the reach rate chart, [group] ahead on 9 of 11 days” is that metric’s over-time chart read: every visitor, unclipped, counted on the days both groups had 100 or more visitors. Pick the same metric in the chart’s menu to see the lines.
- Goal vs money — when a test’s goal is reach rate (did visitors get to a page), the goal still decides the verdict, because sometimes reach really is the point. But when money leans clearly the other way, the banner shows both sides, for example “[group] is earning more, but reaching your goal less”, instead of telling you to stop or ship. A goal result that revenue contradicts without a clear lean reads “Mixed result — keep running”.
- Peek-safe significance — the strict Ship and Keep control calls come from a sequential method that is valid at any look: check the test every day and “statistically significant” still means what it says. Two things follow. The strict calls count only visitors whose attribution window has closed (14 days by default), so a strict call always runs that far behind the visitor count on the cards; the directional reads use every visitor. And a strict revenue call is made on capped gross revenue per visitor — each visitor’s revenue before refunds, capped at the amount set when the test started — while the figures shown stay net of refunds (refunds are a guardrail). There is no minimum number of buyers for a strict call; a group with no buyers simply reads as earning close to nothing. Until a strict call, the banner gives a directional read instead. Strict calls are later and rarer than they were before October 2026; the directional reads are not.
- Tighter estimates — for revenue tests with enough data, Ordinary applies a variance-reduction technique (CUPED) to the estimates and the directional reads, so they settle sooner. The strict calls don’t use it. The math is in the About the math expander.
- Allocation check — the list shows the split actually observed (control first — “52 / 48”), and each group’s card shows its exposed visitors and share of test traffic. If the split looks suspicious (you set 50/50 but actual exposure is 65/35), the dashboard flags it so you don’t trust biased results.
- Notes — every test has a Notes tab: a dated, signed log anyone on your team can add to. Use it for the things the numbers can’t say — the budget change on day two, the afternoon a variant was broken, why you paused, what you decided at the end. Notes stay with the test; a note can be removed by whoever wrote it or by an org admin. If notes cannot load, the tab shows an error with Retry, not an empty log or a misleading zero count. Retrying does not submit a new note.
- Funnel by arm — each step (visitors, add-to-cart, checkout, orders) drawn as a share of that group’s exposed visitors, one bar per group, with the step-to-step advance rate underneath — so you can see WHERE a test wins or loses (a cart-adds win that dies at checkout is a different decision than a checkout-completion win).
- Guardrails — the metrics you chose to watch for damage (refund rate, bounce rate, add-to-cart rate, 30-day repeat purchase, reach rate, revenue per visitor). Each shows both arms, the difference, and a status that understands direction — a refund-rate increase is flagged, not a decrease. Every guardrail is read with the same sequential method as the headline result, valid at any look and counting only visitors whose window has closed. Regressing means the variant is conclusively worse on that metric; Improving means it’s conclusively better — both carry a small “peek-safe” marker, meaning the call comes from that sequential method rather than from a one-off test. Borderline is a move that isn’t conclusive either way, and No regression is the all-clear so far. Metrics that can’t be computed honestly yet (for example repeat purchase before any visitors are 30 days old) say “No data yet” instead of pretending everything is fine.
- Overlap with other tests — how many of this test’s visitors were also in another running test, in total and test by test. Overlap is normal when several tests run at once, and a test that runs on every page overlaps with every other test by construction, so a high share against one of those is expected rather than a problem. Next to the results controls, Exclude visitors also in other running tests re-reads the headline result, the guardrails and the verdict without those visitors. Use it to understand, not to decide: excluding people removes them from the analysis, and when the other test changes where shoppers go on your store, the group that’s left can tilt one way — so the “clean” number can be less trustworthy than the full one, not more. If the verdict holds either way, the overlap is probably harmless; if it flips, the two tests are interacting and are worth separating with an exclusion group. The funnel, trend, value breakdown, profit, ad spend and subgroup panels always keep every visitor, except By ad, which follows the toggle so it always adds up to the group cards. Below the list, Results by the other test’s groups answers the question the overlap count can’t: does the other test change this one’s result? For each overlapping test there’s a small table with one row per group of the other test (plus visitors who never saw it). Each row shows revenue per visitor, buyers and conversion rate for this test’s groups, and this test’s lift within that row. If the lift is about the same in every row, the other test isn’t changing this result. If it’s flat in one row and large in another, this test only works in combination with one version of the other test, so decide the two together. Effect differs by group appears when that difference is clear rather than noise. Groups not split independently appears when visitors in one group here landed in one group of the other test more often than chance; compare lifts within a row rather than the overall numbers. Like the subgroup panels it’s exploratory, counts whole orders net of refunds and isn’t outlier- clipped, so it can differ slightly from the group cards. Best so far, above the tables, names the winning group of each test when up to three other tests overlap. It weighs all of them together, so it can disagree with a single table: a test that only helps alongside a losing version of another test gets no call once that loser is out. Each name carries Clear (the range rules out no difference), Early sign (pointing one way, not yet certain), Too close or Too early (under 10 buyers on a side). The cell it names is tinted green, and the original version of every test is marked “(original)”.
- Subgroup cross-cuts — the same lift sliced by channel, visitor type, device, geography, page and ad, marked exploratory because the test wasn’t designed around any one slice. Visitor type is new vs returning as the pixel classified each visitor when they first saw the test: a browser with no earlier visit on record counts as new. That’s a different rule from the returning-visitor audience filter on the Targeting tab, which counts sessions, so a returning-only test can enrol a slightly different group than this slice shows.
- By ad — the test’s visitors grouped by the Meta ad or Google campaign on the link they arrived through, both groups side by side: visitors, buyers, net revenue and revenue per visitor, plus the lift and its likely range. On a landing-page test this holds the ad the same and varies only the page, so each row answers “for people who clicked this ad, which page earned more?”. Split by the test marks the ads that pointed at the test’s page while it ran (where Ordinary has a record of where the ad pointed), and the first row adds those up. Meta ads sit under their campaign; Google’s links name only the campaign, so Google traffic is grouped by campaign. An ad click whose link carried no ad id has its own “not identified” row, and No ad is everyone else — organic, email and direct. The rows use the same visitors, attribution window and net-of-refunds revenue as the group cards, so the last row, All visitors, matches them. A group too small to estimate shows “Too few to tell”, and past the first ten the rest are added into one row.
- Value breakdown — where a revenue move came from: average order value, units per order, product and shipping revenue per order, discounting, orders refunded so far, subscription share, and repeat purchases inside the window. These are raw order values (not outlier-capped) net of refunds, so its average order value matches the group cards whenever they show raw revenue. Shipping revenue is what was charged less shipping refunded, and “orders refunded so far” counts orders where money went back to the customer. Diagnostic by design — the winner call stays with the headline lift.
- Profit per visitor — each arm’s profit, worked out the same way as everywhere else in Ordinary: the arm’s revenue net of refunds (the group cards’ revenue) and before tax, less what the items the customer kept cost when they were sold (from the costs already on your catalog — no separate COGS entry step), less your per-order costs from Settings → Product Costs: fulfilment, shipping, and payment fees on the revenue after refunds. The table shows the revenue, the tax inside it and the revenue before tax, so the arithmetic is on screen. A returned item’s cost comes off with its revenue; an item removed by an order edit never shipped, so it costs nothing. Then margin, profit per visitor and per order. With no per-order costs entered the rows read Gross profit, with a link to add them. A ≤ in front means an item that sold for money has no cost, so the true figure is at most that; items given away free with no cost are counted beside the goods cost instead. If cost coverage on an arm is below 70% of revenue, Ordinary shows the coverage figure and how to raise it instead of a misleading number. This card needs the Financials or Offer Calculator feature — without it the rest of the results are unchanged and this one card is a blurred preview.
- Ad spend context — what the store spent on Meta and Google while the test ran, each arm’s paid-traffic share, new customers, and effective cost per new customer, plus what the observed lift range would mean per month at your recent revenue pace (net of refunds) — spend and test results on one surface.
- Revenue per visitor over time — a line per variant showing revenue per visitor to date: each day’s point covers everything from launch through that day, so the last point is the test’s result so far. Lines jump around in the first few days, then settle. Lines that settle apart mean a steady difference; lines that keep crossing mean the result isn’t settled yet. The last day or two often dip slightly, because the newest visitors haven’t had their full attribution window to buy. The dropdown at the top right of the card switches the metric — revenue per visitor, conversion rate, average order value, orders per buyer, profit per visitor or reach rate — and the expand button beside it shows all six side by side, each drawn the same way. That’s useful on a lower-traffic store: before the test can be called, you can still see whether one group sits above the other day after day. Lines are dashed until a group has 100 visitors. A metric only starts on the day every group has a figure for it (average order value needs an order in each group), profit per visitor needs product costs on your plan, and reach rate needs a reach goal page set on the Analytics tab.
Every number uses the same reconciled revenue and attribution as the rest of your reports — every order counted is a real, paid Shopify order, and the refunds recorded against it are taken out.
How to interpret “Too early”
Ordinary won’t pretend a test is significant when it isn’t. In the experiments list a test reads “Too early” until at least 1,000 visitors have been exposed to it; after that it reads “Variant ahead” or “Control ahead” — which group is ahead right now, a glance, not a verdict. On the experiments card on Brand Pulse a test reads “Too early to call” until each group has at least 5 buyers and 20 between them. The verdict is the banner at the top of the test’s own page: it says whether a winner can be called, which way the test leans on money, or to keep running.
To plan a test before running it, use the sample size calculator — it’s the button next to the Pause / End controls at the top of any test, and it’s public, so you can use it before you’ve built anything. Plug in your baseline conversion rate and the smallest lift you’d want to detect, and it tells you how many visitors per variant you need.
Settings and defaults
Open Settings → Experiments for org-wide settings:
- Default guardrails — secondary metrics checked alongside the primary so you catch trade-offs (a variant might “win” on conversion rate but lose on refund rate, which is a wash). New tests start with these.
- About the math we use — how Ordinary calculates results and calls a winner.
Each test’s own primary metric, guardrails and attribution window are set on its Goals tab.
How content changes reach your storefront
Tests take one of two routes to your live store, depending on what the variant changes.
Styling and visibility changes — colour, size, spacing, hiding something — are applied as the page loads. Nothing in your theme changes.
Content changes — a different headline, a different image, a changed link — are made in your theme. Ordinary places them when the test starts (or when you publish from the visual editor), and the test only goes live once they’re in place. If Ordinary doesn’t have permission to edit your theme, the test doesn’t start and nothing on your store changes: reconnect Shopify from Settings, approve theme access, and start the test again. The Theme changes tab on a test shows whether that test changed your theme.
Every theme edit:
- Only adds. Your original wording stays exactly as you wrote it. Ordinary puts the variant alongside it, so a shopper sees one or the other. Nothing of yours is replaced or deleted. If a change can’t be made that way, Ordinary won’t make it.
- Is backed up first. Ordinary saves your theme exactly as it was before changing anything, so it can be put back exactly.
- Is checked, and undone if anything’s wrong. Ordinary checks your page after the edit. If it doesn’t come out right, the change is removed and the test doesn’t start.
Everything Ordinary adds is labelled as ours and kept together, so it’s easy to spot in the theme editor.
Seeing exactly what changed
Open the test and go to Theme changes. It lists every file Ordinary touched for that test and shows the change line by line, the way a developer would review any other edit — added lines marked, your original lines alongside them. Each file shows when the change was made and whether it’s still in place.
If a test has never changed your theme, the tab says so.
Removing a test’s changes from your theme
Ordinary does not remove them on its own — not when you end a test, and not when you uninstall. They stay in your theme until you take them out, so that ending a test never quietly edits your files.
To take them out: open the test, go to Theme changes, and click Remove from theme. Each file goes back exactly as it was before the change.
If a saved file has been deleted, Remove from theme can recreate it in the theme it originally came from, even if you deleted it intentionally. It will not recreate a file merely because Shopify cannot read it. Avoid editing the same file in Shopify while removal is running.
What stays behind until then does nothing. Once a test isn’t running, the alternative versions stay hidden and every shopper sees your original content. There’s nothing broken in the meantime — it’s your own wording on the page either way.
If you’ve edited the file yourself since Ordinary changed it, Ordinary won’t overwrite your work. It stops and tells you it couldn’t put that file back, rather than risk removing something you wrote. Get in touch and we’ll help you sort it out.
Before you uninstall: an uninstalled app can no longer edit your store, so remove the changes first if you want them gone. If you’ve already uninstalled, reinstall and remove them, or contact support and we’ll walk you through taking the labelled blocks out by hand.
Which parts of your theme change
Only your live theme, and only the section your tested headline, image or link sits in. Ordinary never touches your theme settings, your templates, or your uploaded files. If it can’t tell for certain which part of your theme creates what you picked, it won’t start the test.
Data coverage and cookie consent
Experiment data is captured via the same pixel events that power the rest of Ordinary’s analytics. If your storefront uses a cookie banner integrated with Shopify’s Customer Privacy framework — common for EU/UK/EEA-facing stores — shoppers who decline cookies generate no pixel events, so they’re invisible to the experiments platform.
In practice:
- Sample sizes for tests with strict-region traffic will be lower than your overall visitor count suggests. Plan accordingly.
- The shoppers in your results are the accept-cookies subset. People who decline might behave differently — a technical selection bias, but every analytics platform on Shopify has the same limitation, and the framework is what Shopify requires for compliance.
- Non-strict-region traffic (US, Canada, Australia, most of Asia and South America outside specific markets) sees no banner by default and produces a full event stream.
If a test needs a specific sample size, factor in your accept-cookies rate. A test with 40% EU traffic and a 60% accept rate captures roughly 76% of your visitors — plan for ~30% more traffic, or run it ~30% longer.
See How Ordinary handles your visitor and customer data for the full posture.
Split your other reports by variant
While a test runs, Ordinary can split your existing reports by variant. Look for the Experiment dropdown in the page actions on Orders and Customers — selecting a test breaks every row out by which variant the visitor saw. Handy for spot-checking that the per-variant aggregates agree with live order data.
Frequently asked
Q: My test isn’t collecting data. Why not?
A: If it’s a test you built in Ordinary, make sure you clicked Start (drafts don’t run) and that real traffic is hitting the URL pattern you set — give it ~10 minutes after the first shopper lands. If a test is running but the Results tab stays empty for longer than that, contact support with the test name and we’ll trace it.
Q: Can I change the traffic split while a test is running?
A: Yes — that’s how you ramp a rollout. Move the split on the Test groups tab and save; shoppers already in the test keep their group, and only new visitors are divided by the new percentages. The allocation check scores each split separately from the moment you save it, so a deliberate ramp doesn’t read as a traffic-split problem. Setting a group to 0% stops new traffic reaching it without ending the test. What stays fixed once a test starts: which groups exist, and where they point.
Q: I changed my test variants mid-flight. What happens?
A: Changing the content of a variant (as opposed to its traffic share) is a different matter. Ordinary flags this as an assignment conflict on the affected visitor records and surfaces a warning if the conflict rate is non-zero. Best practice is to end the original test and start a fresh one rather than reshuffling buckets — but Ordinary won’t quietly mix the data.
Q: How long does Ordinary count an order as belonging to a test?
A: 14 days from when a shopper first saw a variant, by default. On that setting a purchase 18 days after exposure falls outside the window and isn’t attributed to the test. You can change the window per test on the Goals tab (1, 7, 14, 30 or 90 days).
Related articles
- Page Performance — a split-URL test’s variant arm appears as its own version of the page there, with a link back to the test’s report.
- Setting up landing-page angles — angles vs tests, and how an angle becomes a test arm.